← Retour au fil
L'IOTA SDK démontre un entraînement cohérent sur des GPU distribués malgré 585 interruptions de workers
TAO Daily27 oct., 02h · il y a 5j

L'IOTA SDK démontre un entraînement cohérent sur des GPU distribués malgré 585 interruptions de workers

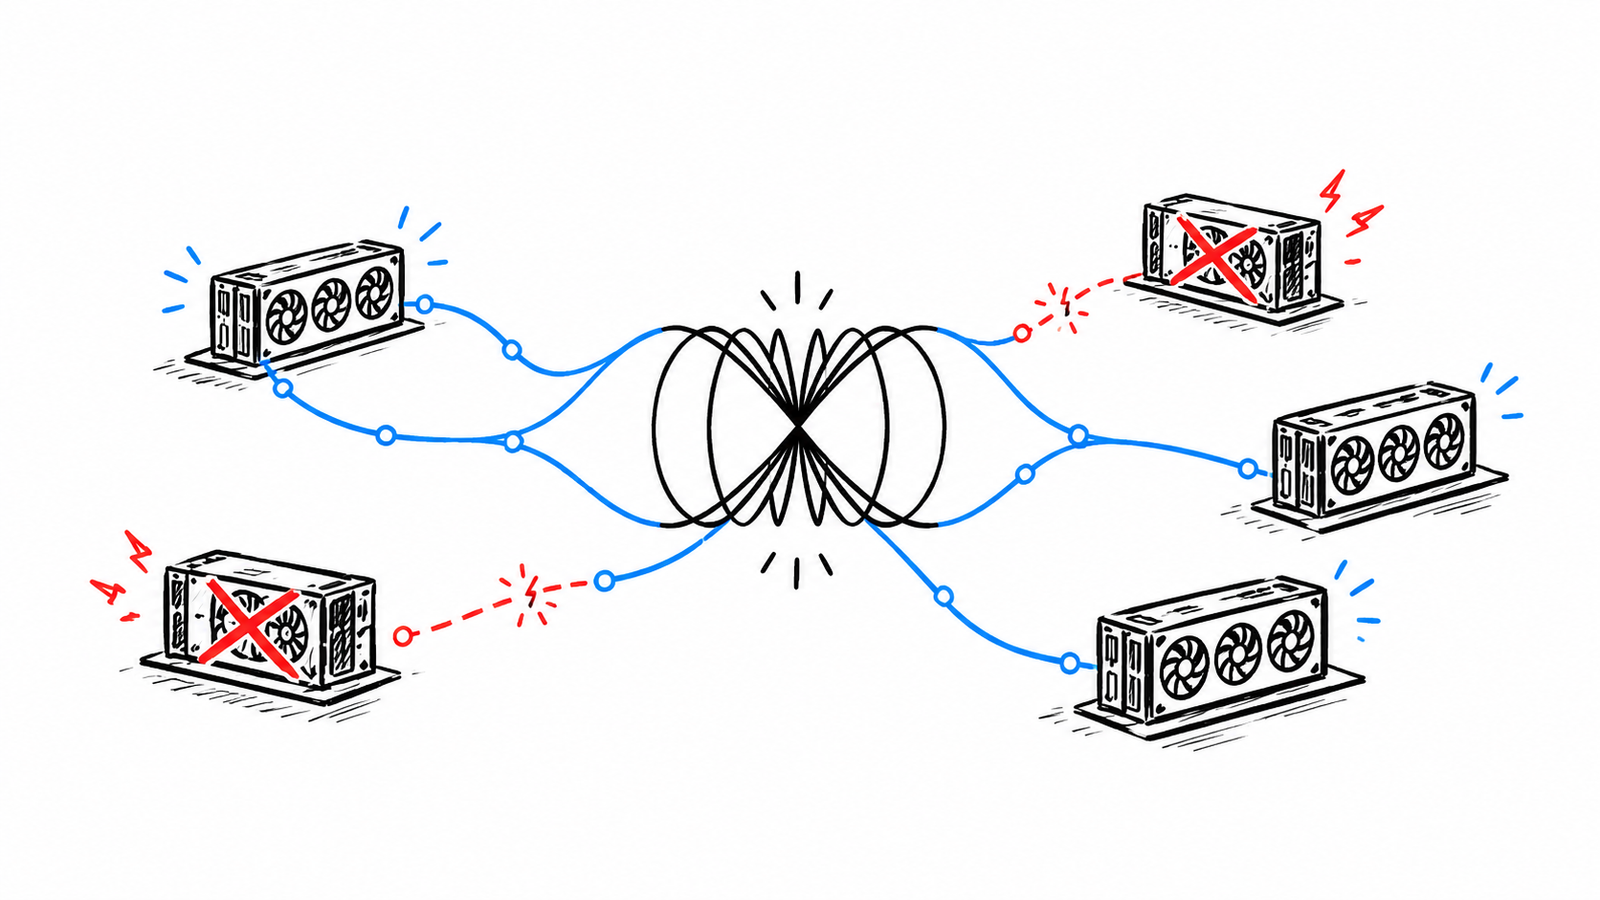
585 pannes, 140 GPU, sept runs et des courbes quasi identiques : l'IOTA SDK de Macrocosmos montre qu'un entraînement d'IA décentralisé peut encaisser les crashes sans dévier.

Macrocosmos a partagé les résultats de son IOTA SDK (subnet SN9) : sept entraînements indépendants d'un modèle à 16 milliards de paramètres, chacun réparti sur environ 140 GPU distribués. Malgré 585 crashes, préemptions et reconnexions de workers, les sept runs ont produit des courbes de loss quasi identiques, preuve d'un apprentissage stable malgré les interruptions.

Le SDK coordonne l'entraînement sur des GPU opérés indépendamment via data et pipeline parallelism, avec une orchestration qui gère les pannes. Présenté à l'Exploit Summit de Montréal autour de workflows PyTorch, il complète l'initiative Train at Home. Limite : la reproductibilité du comportement est démontrée, pas celle des poids du modèle, et aucun gain de coût ou de performance n'est établi face aux infrastructures classiques.

Bittensor

Détails

Source
TAO Daily
Publication
27 oct. à 02h34

Contenu source (brut)

<p class="wp-block-paragraph">What happens when a GPU crashes halfway through training an AI model? And can developers trust the results when hundreds of machines are working together across different locations?</p> <p class="wp-block-paragraph">These are among the concerns raised about the reliability of decentralized AI training. <a href="https://taodaily.io/macrocosmos-says-liquid-training-could-turn-idle-gpus-into-frontier-ai-compute/">Macrocosmos</a> has now shared experimental results showing how its <a href="https://taodaily.io/iota-sdk-to-let-ai-developers-tap-distributed-gpus-without-rebuilding-their-workflows/">IOTA SDK</a> addresses these challenges.</p> <figure class="wp-block-image size-large is-resized"><img fetchpriority="high" decoding="async" width="1024" height="399" src="https://taodaily.io/wp-content/uploads/2026/10/image-254-1024x399.png" alt="" class="wp-image-25891" style="aspect-ratio:2.567901234567901;width:624px;height:auto" srcset="https://taodaily.io/wp-content/uploads/2026/10/image-254-1024x399.png 1024w, https://taodaily.io/wp-content/uploads/2026/10/image-254-300x117.png 300w, https://taodaily.io/wp-content/uploads/2026/10/image-254-768x299.png 768w, https://taodaily.io/wp-content/uploads/2026/10/image-254.png 1892w" sizes="(max-width: 1024px) 100vw, 1024px" /><figcaption class="wp-element-caption"><a href="https://iota.macrocosmos.ai/sdk">IOTA SDK’s Website</a></figcaption></figure> <p class="wp-block-paragraph">In seven independent training runs of a 16-billion-parameter model, approximately 140 GPUs participated in each experiment.</p> <p class="wp-block-paragraph">Across the runs, workers experienced 585 crashes, preemptions, and rejoins. Yet all seven experiments produced nearly identical training loss curves, showing that the model&#8217;s learning progress remained consistent despite repeated interruptions.</p> <figure class="wp-block-image size-large is-resized"><img decoding="async" width="1024" height="483" src="https://taodaily.io/wp-content/uploads/2026/10/image-255-1024x483.png" alt="" class="wp-image-25892" style="aspect-ratio:2.1152542372881356;width:624px;height:auto" srcset="https://taodaily.io/wp-content/uploads/2026/10/image-255-1024x483.png 1024w, https://taodaily.io/wp-content/uploads/2026/10/image-255-300x141.png 300w, https://taodaily.io/wp-content/uploads/2026/10/image-255-766x361.png 766w, https://taodaily.io/wp-content/uploads/2026/10/image-255.png 2048w" sizes="(max-width: 1024px) 100vw, 1024px" /><figcaption class="wp-element-caption"><a href="https://x.com/IOTA_SN9/status/2113723927075721451/">Runs on IOTA SDK</a></figcaption></figure> <p class="wp-block-paragraph">This consistency is particularly important for researchers and companies paying to train AI models.</p> <p class="wp-block-paragraph">If the same experiment produces significantly different results because machines disconnect, it becomes harder to verify findings or justify training expenses.</p> <p class="wp-block-paragraph">IOTA&#8217;s results demonstrate reproducibility in training behaviour, although they do not establish that the resulting model weights were identical.</p> <p class="wp-block-paragraph"><a href="https://taodaily.io/iotas-orion-100b-still-proves-frontier-training-doesnt-need-one-giant-data-centre/">IOTA (SN9)</a>, developed by <a href="https://taodaily.io/macrocosmos-makes-the-case-for-liquid-training-over-bigger-gpu-clusters/">Macrocosmos</a>, is designed to coordinate AI training across independently operated GPUs. It uses data parallelism and pipeline parallelism to divide training work among machines, allowing them to process different portions of a model without each GPU needing enough memory to hold the entire model.</p> <p class="wp-block-paragraph">The subnet also accounts for unreliable hardware. When a participating GPU becomes unavailable or abruptly disconnects, IOTA&#8217;s orchestration system manages the disruption and coordinates recovery so training can continue.</p> <p class="wp-block-paragraph">This capability was central to the seven experiments, which tested whether repeated worker failures would significantly affect training outcomes.</p> <p class="wp-block-paragraph">Macrocosmos introduced the IOTA SDK at the <a href="https://taodaily.io/iota-sdk-to-let-ai-developers-tap-distributed-gpus-without-rebuilding-their-workflows/">Exploit Summit in Montreal</a> to make this infrastructure accessible to developers. Through an interface designed around familiar PyTorch workflows, teams can specify their model, dataset, and training objectives while the underlying network manages distribution, execution, monitoring, and recovery.</p> <p class="wp-block-paragraph">The SDK also complements <a href="https://taodaily.io/training-at-home-launch-macrocosmos-introduces-iotas-way-of-powering-ai/">IOTA&#8217;s Train at Home</a> initiative, which allows individuals with compatible consumer GPUs to contribute computing power to larger training workloads.</p> <p class="wp-block-paragraph">The system combines resources from multiple contributors without requiring every participant to own expensive enterprise hardware. The SDK gives developers a way to use that distributed capacity.</p> <figure class="wp-block-image size-large is-resized"><img decoding="async" width="1024" height="485" src="https://taodaily.io/wp-content/uploads/2026/10/image-256-1024x485.png" alt="" class="wp-image-25893" style="aspect-ratio:2.108108108108108;width:624px;height:auto" srcset="https://taodaily.io/wp-content/uploads/2026/10/image-256-1024x485.png 1024w, https://taodaily.io/wp-content/uploads/2026/10/image-256-300x142.png 300w, https://taodaily.io/wp-content/uploads/2026/10/image-256-768x364.png 768w, https://taodaily.io/wp-content/uploads/2026/10/image-256.png 1888w" sizes="(max-width: 1024px) 100vw, 1024px" /><figcaption class="wp-element-caption"><a href="https://iota.macrocosmos.ai/train-at-home/dashboard">IOTA Train at Home Dashboard</a></figcaption></figure> <p class="wp-block-paragraph">For AI companies, the potential advantage is access to large-scale training infrastructure without having to assemble and operate an entire GPU cluster.</p> <p class="wp-block-paragraph">However, the seven experiments primarily demonstrate training consistency under worker disruptions. They do not independently establish lower costs or superior performance compared with conventional training infrastructure.</p> <p class="wp-block-paragraph">The significance of Macrocosmos&#8217; demonstration is that it addresses a practical requirement for decentralized AI training to become useful beyond individual experiments.</p> <p class="wp-block-paragraph">Training a large model once is an achievement, but consistently reproducing the results despite worker failures is more significant. It provides stronger evidence that IOTA can support serious AI research.</p> <p class="wp-block-paragraph">➛ Register Your Interest in the IOTA SDK <a href="https://iota.macrocosmos.ai/sdk">Here</a>.</p> <figure class="wp-block-embed is-type-wp-embed is-provider-the-tao-daily wp-block-embed-the-tao-daily"><div class="wp-block-embed__wrapper"> <blockquote class="wp-embedded-content" data-secret="lxdgoZ1LPy"><a href="https://taodaily.io/iota-sdk-to-let-ai-developers-tap-distributed-gpus-without-rebuilding-their-workflows/">IOTA SDK To Let AI Developers Tap Distributed GPUs Without Rebuilding Their Workflows</a></blockquote><iframe class="wp-embedded-content" sandbox="allow-scripts" security="restricted" style="position: absolute; visibility: hidden;" title="“IOTA SDK To Let AI Developers Tap Distributed GPUs Without Rebuilding Their Workflows” — The TAO Daily" src="https://taodaily.io/iota-sdk-to-let-ai-developers-tap-distributed-gpus-without-rebuilding-their-workflows/embed/#?secret=J1BlEWWhrB#?secret=lxdgoZ1LPy" data-secret="lxdgoZ1LPy" width="500" height="282" frameborder="0" marginwidth="0" marginheight